- 홈페이지 /
- 서적 /
- 컴퓨터 및 기술 /
- 컴퓨터 과학 /
- AI & Machine Learning /
- Intelligence & Semantics /
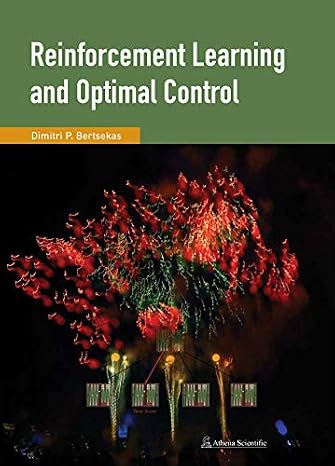
- Reinforcement Learning and Optimal Control
0 ratings


제품번호 #:
17157855
Reinforcement Learning and Optimal Control
88% of respondents would recommend this to a friend
제품번호 #:
17157855
KRW 178321
Price Details
Excluding Shipping & Custom charges ( Shipping and custom charges will be calculated on checkout )
*All items will import from 미국
0 ratings
리뷰 작성
재고
 USA 스토어에서 가져옴
QTY:
지금 주문하시면 도착 예정일 목요일, 10월 15
Secured transaction
Ubuy works hard to protect your security and privacy. Our advanced payment security system ensures confidentiality by encrypting your information during transmission using AES (Advanced Encryption Standards) and SSL (Secure Socket Layer) protocols. Your payment details are 100% secure as we do not share your payment details with third party sellers.
Our Top Logistics Partners


Reinforcement Learning, Approximate Dynamic Programming, and Neuro-Dynamic Programming are solution methods for large and complex decision problems.

Fast
Shipping

Free
Return*

Secure Packaging

100% Original Products

PCI DSS Compliance

ISO 27001 Certified



Note: Step Down Voltage Transformer required for using electronics products of 미국 store (110-120). Recommended power converters 지금 구매.


What Stands Out
Comprehensive Framework
Offers an integrated approach combining reinforcement learning with optimal control, addressing both theoretical concepts and practical applications for enhanced understanding and implementation in various contexts.
Real-World Applications
Equips readers with the necessary tools and methodologies to apply reinforcement learning techniques in real-world scenarios, ensuring relevance and usability in contemporary automated systems.
Expert Contributions
Authored by leading experts, this book provides authoritative insights and cutting-edge research, ensuring high-quality content that meets the needs of both academics and practitioners in the field.
제품 세부 정보
- Addresses large and complex multistage decision problems
- Offers solution methods based on approximations for suboptimal policies
- Explores the intersection between artificial intelligence and optimal control
- Organizes successful methods with solid theoretical foundations
- Provides intuitive explanations and numerous examples
- Suitable for self-study or as a textbook with supporting materials
| Publisher | Athena Scientific |
| Publication date | July 15, 2019 |
| Edition | First Edition |
| Language | English |
| Print length | 388 pages |
| ISBN-10 | 1886529396 |
| ISBN-13 | 978-1886529397 |
| Item Weight | 1.48 pounds (670 grams) |
| Dimensions | 10 x 8 x 1.5 inches (25.4 x 20.3 x 3.8 cm) |
Who Should Buy?

-
Academic Researchers
Ideal for researchers focusing on reinforcement learning and control theories to advance their studies and projects.
-
Graduate Students
Beneficial for graduate students in computer science or engineering seeking to deepen their understanding of optimal control.
-
Industry Professionals
Useful for professionals in AI or robotics looking to implement reinforcement learning for practical applications.

-
Casual Learners
Not suitable for those seeking basic introductions or quick tutorials on reinforcement learning fundamentals.
제품 설명
Reinforcement Learning and Optimal Control
질문이 있으십니까? 채팅하기
고객 질문 및 답변
-
의문:
Ubuy에서 온라인으로 Reinforcement Learning and Optimal Control 쇼핑하는 방법?
답변: Ubuy에서 온라인으로 Reinforcement Learning and Optimal Control을(를) 쉽게 쇼핑할 수 있습니다.. 제품을 검색하고 체크아웃하는 동안 배송 방법을 선택하고 해당 위치로 배송받기만 하면 됩니다. -
의문:
Reinforcement Learning and Optimal Control는 South Korea에서 온라인 쇼핑이 가능합니까?
답변: 예, Ubuy South Korea에서 이 제품을 합리적인 가격에 구매할 수 있습니다.. Reinforcement Learning and Optimal Control은(는) 현지에서 구할 수 없지만 특급 배송 서비스로 저희를 신뢰할 수 있습니다. -
의문:
주문 후 제품을 받는 데 얼마나 걸립니까?
답변: 주문한 제품의 배송 시간은 주문한 항목과 선택한 배송 방법에 따라 다릅니다.. 예상 배송 시간은 결제 과정에서 언급되므로 안심하고 쇼핑하십시오.
Intelligence & Semantics Editorial Review
The Reinforcement Learning and Optimal Control First Edition by Bertsekas is praised for its technical expertise and mastery of exposition. The book offers clear explanations of the key ideas behind RL and optimal control and the differences between machine learning and traditional adaptive control approaches. The algorithms are thoroughly explained and made transparent. It is recommended for readers with a basic background in dynamic programming or control theory. The book is regarded as a must-read for anyone who wants to understand RL. The author uses a broad range of examples to guide readers starting from exact DP for finite-horizon problems. The book provides an understanding of RL for finite-horizon problems and DP and RL theory for infinite-horizon problems. The author also presents the aggregation method and its special characteristics. The book is good at explaining the theory of finite-state and finite-action problems in a self-contained and rigorous manner. The author reminds readers throughout the book that the potential challenges lie in the implementation of theoretical techniques.
Customer Reviews & Ratings
1 고객 평가
-
5 점
100%
-
4 점
0%
-
3 점
0%
-
2 점
0%
-
1 점
0%
이 제품 리뷰하기
다른 고객들과 의견을 공유하세요.
장점
- Technical expertise and mastery of exposition.
- Clear explanations of key ideas behind RL and optimal control.
- Thoroughly explained algorithms.
- Wide range of examples to guide readers.
- Provides an understanding of RL for finite-horizon problems and DP and RL theory for infinite-horizon problems.
- Explains the aggregation method and its special characteristics.
- Self-contained and rigorous.
Product Price History
중요 정보
- 제한 사항: 국제 배송되는 제품의 경우 제조업체 보증이 유효하지 않을 수 있으며, 제조업체 서비스 옵션을 사용하지 못하거나 제품 설명서, 지침 및 안전 경고가 대상 국가 언어로 표시되지 않을 수 있으며, 제품(및 첨부 자료)은 도착 국가 표준, 사양 및 라벨링 요구 사항에 따라 설계되지 않을 수 있으며, 제품은 목적지 국가 전압 및 기타 전기 표준을 준수하지 않을 수 있습니다(가능한 경우 어댑터 또는 변환기 사용 필요). 수령인은 제품을 도착 국가로 합법적으로 수입할 수 있는지 확인할 책임이 있습니다. Ubuy 또는 그 제휴사에서 주문할 때, 수령인은 기록 수입자로서 도착 국가의 모든 법률과 규정을 준수해야 합니다.
- Ubuy는 글로벌 검색 엔진이므로 Ubuy에 나열된 모든 제품이 판매용은 아닙니다. 제품은 수출/무역 규정을 따릅니다.
KRW 178321
지금 주문하시면 도착 예정일 목요일, 10월 15
This item is not restrict in my country.(Please click on above link if this item is not restrict in your country, So our team will review and allow.)
QTY:
Secured transaction
PCI DSS compliant and ISO 27001:2022 certified, with encrypted payments and full buyer protection on every order.
Our Top Logistics Partners
Fastest cross-border delivery
특징 및 장점
- Consideration of large multistage decision problems
- Focus on solution methods for suboptimal policies
- Explore the border between artificial intelligence and optimal control
- Organized coherent summary of successful methods
- Combination of rigor and intuitive explanations
- Mathematical theory illustrated with algorithms and applications
Ubuy Assurance
Experience worry-free shopping with 100% original products, PCI DSS-compliant payment security, ISO 27001-certified data protection, the fastest cross-border delivery, free returns *, and secure packaging on every order.